 XMOHAN
Contextual interpretation of video
Deep-learning methods for extracting contextual indicators from scenes, motion and visual atmosphere rather than relying exclusively on conventional image-object labels.
Beginning in the 2010s, my research and company-building at Skive it, Inc. explored whether machine perception could recognize contextual qualities of real-world experiences—such as atmosphere, style and mood—and make those qualities searchable.
Skive it publicly framed its mission as building autonomous AI systems that can feel. In research terms, the immediate technical work explored machine recognition and representation of the contextual and emotional characteristics of human experiences; that ambition should not be mistaken for evidence of subjective machine feeling.
A conventional visual search system may recognize objects, faces or locations. Skive it asked a different question: can machine learning extract useful context about the feel of an experience from video? The company described a semi-unsupervised deep-learning approach for interpreting contextual style, mood and sentiment from near-real-time video, then exposing those representations to natural-language search.
The original ambition was to make experiences searchable by qualities such as cozy, lively, romantic, relaxed, practical or retro—not merely by venue type, product category or geolocation. These were proposed and developed technical directions; their accuracy, generality and inference characteristics should not be assumed without independent evaluation.
Deep-learning methods for extracting contextual indicators from scenes, motion and visual atmosphere rather than relying exclusively on conventional image-object labels.
Investigating how video and human-provided descriptors can support context-sensitive representation learning, including the company's historical semi-unsupervised approach.
Linking visual or affective descriptors to queries about the kind of experience a person wants, such as finding a quiet cafe or a lively evening venue.
A mood- and style-oriented search engine for places and experiences. The historical site described it as live, providing a public interface for searching venues by contextual character rather than only standard categories.
A city and experience discovery system combining curated local knowledge with the broader aim of letting people explore a place's atmosphere before visiting. It featured cities in North America and East Asia.
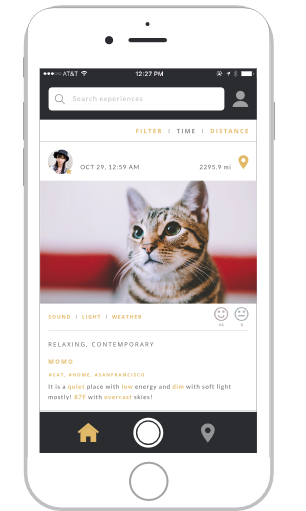
The Skive it mobile app reached Beta. Its interface combined visual posts with time and location cues, contextual descriptors and signals such as sound, light and weather. The preserved image shows an early Beta interface with mood and style labels. Beta status is not a claim of a completed general public app-store release.
These systems also served the research objective of encountering more diverse real-world examples and feedback relevant to training and evaluating contextual perception.
The company articulated a longer-term vision for a specialized AI system-on-chip (SoC) capable of supporting robot perception of contextual and emotional cues. The aspiration was to move beyond identifying what is present in a scene toward modeling why an interaction matters to a human companion and how a robot ought to respond.
The publicly described Robometrics® chip was a proposed technology direction, including ideas about learning and adaptation over time. The archived description does not, by itself, establish that a custom chip was fabricated, achieved continuous learning, or produced machine feeling. Recognizing or modeling emotion is also not equivalent to subjective emotional experience.
The research questions behind Skive it—contextual perception, semantic interpretation of experience, adaptation and human-centered intelligent behavior—connect naturally to later work at Robometrics® Machines and the independent Robometrics® AGI lab. The organizations and programs remain distinct, and newer research claims should be judged on their own evidence.
Current research on emotion, instinct and context-sensitive judgment →